Booking Links, Round-Robin and Routing: Scheduling for Small Teams
 DEMOCRAZY News
23 September 2026 1:25 am
.
4 menit membaca
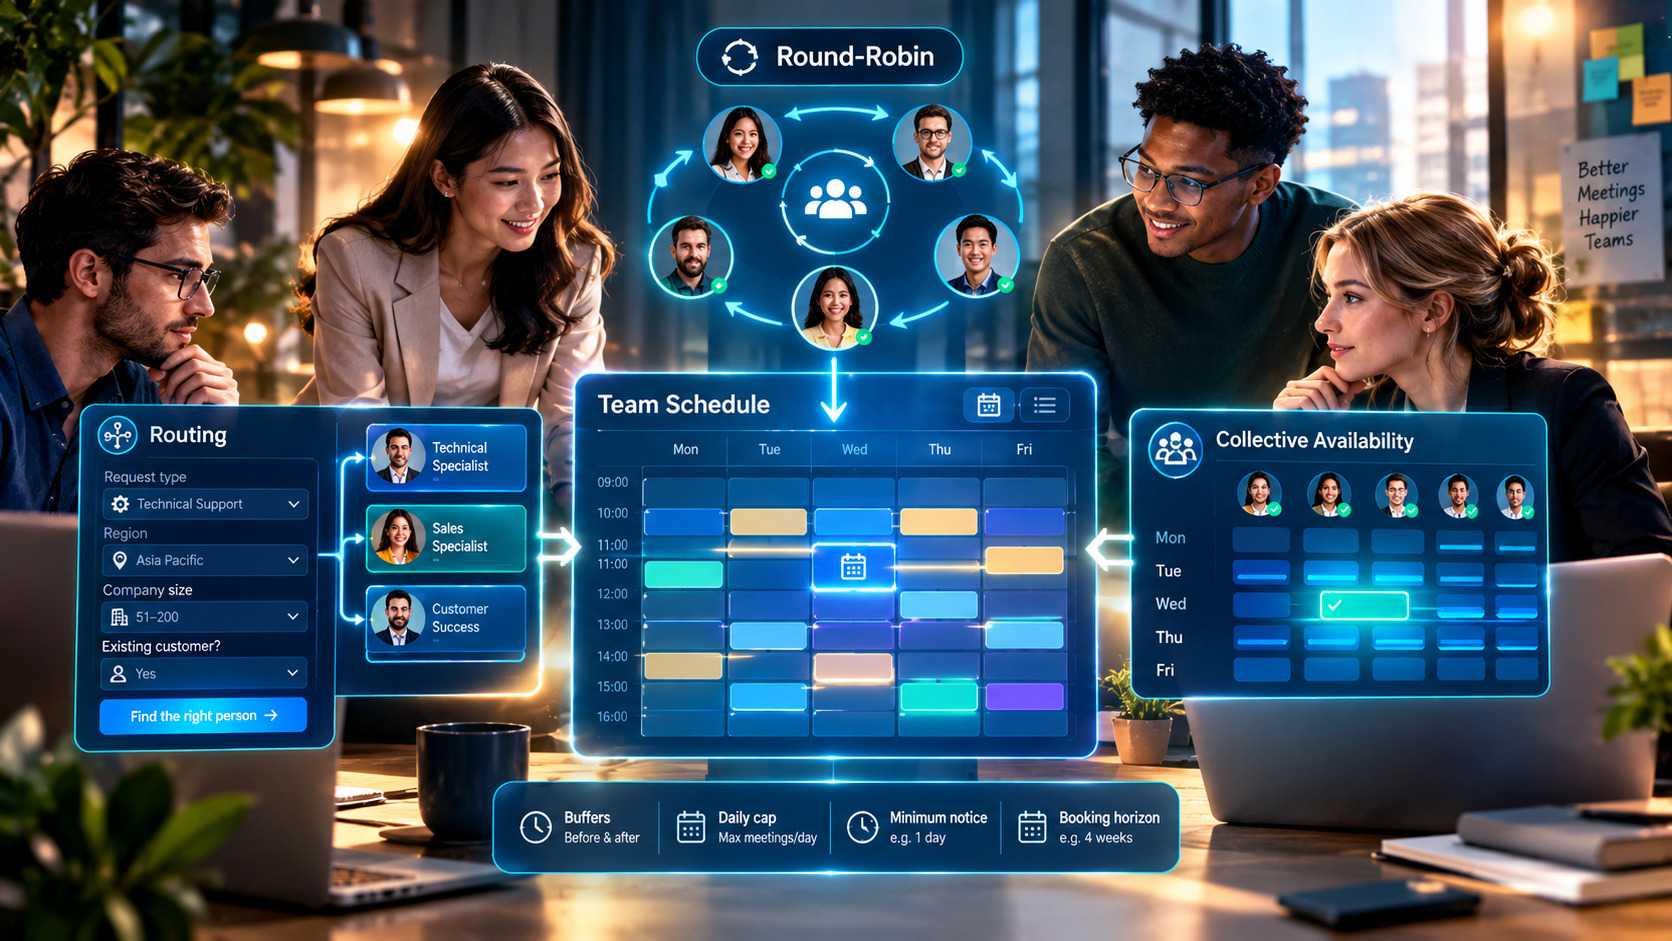
A personal booking link works perfectly for one person and breaks the moment a second is involved.
The requests keep arriving at whoever’s link is published, that person becomes the bottleneck, and the rest of the team is idle while the calendar of one is full.
Fixing this is a configuration problem rather than a tooling one, and it has three moving parts that are frequently confused with each other.
The three mechanisms
| Mechanism | Answers | Use when |
|---|---|---|
| Round-robin | Which team member gets this? | Anyone on the team can handle it |
| Routing | Where should this request go at all? | Different requests need different people |
| Collective availability | When are several people free together? | The meeting needs more than one of you |
Teams usually reach for round-robin first because it is the simplest, then discover that it distributes the wrong things evenly.
Sending a technical question to whoever is next in rotation is fair and unhelpful.
Routing comes before distribution
Routing asks a short set of qualifying questions on the booking form and sends the request to the right place based on the answers — region, product, company size, existing customer or not.
Configured with meeting routing, a request that needs a specialist reaches one directly instead of reaching a generalist who then has to rebook it.
Keep the form short. Every additional question costs conversions, and three well-chosen ones route more accurately than eight vague ones. Ask only what actually changes the destination.
Round-robin, and the ways it goes wrong
Within a pool of people who can all handle a request, round robin scheduling distributes bookings across them.
Baca Juga
Three details decide whether it feels fair:
- Optimise for availability or for equal distribution. Availability-first fills slots sooner; distribution-first keeps the workload even. Pick deliberately — the difference shows up within a week.
- Weighting. A part-time member should not receive the same share as a full-time one.
- Ownership. A returning contact should usually reach the person they met last time. Without this rule, round-robin actively degrades the relationship.
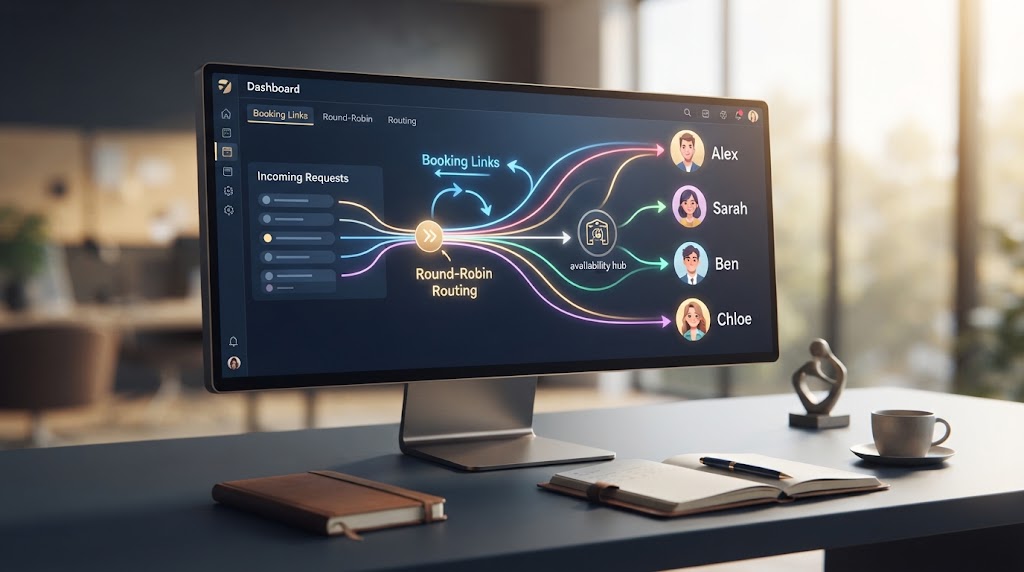
Availability is the foundation everything rests on
Both mechanisms read from each person’s stated availability, and this is where most real failures originate.
A calendar that says free when the person is not produces bookings nobody can honour, and the fix is not in the scheduling tool.
Four settings in availability do most of the work:
- Buffers. Time before and after each booking. Without them, a day of back-to-back calls has no room for notes or travel.
- Daily caps. A maximum number of meetings per day per person. This single setting prevents most burnout complaints about shared booking links.
- Minimum notice. How far ahead someone must book. Two hours is usually too short; a full day is usually right for external calls.
- Booking horizon. How far out the calendar opens. Beyond about four weeks, commitments change and no-shows rise.
Rolling it out without irritating the team
Start narrow. Put one request type through routing, leave everything else as it is, and run it for two weeks.
Check three things: whether requests reached the right person, whether distribution was even, and whether anyone’s day became unworkable.
Then expand one type at a time. Teams that configure everything at once cannot tell which rule caused which problem, and the usual outcome is that the whole system gets switched off.
Rules worth setting on day one
Someone owns the configuration — not everybody, one person. Changes to routing rules get announced, because a silent change looks like a bug to whoever stops receiving bookings.
Every pool has a fallback for when nobody is available, and the fallback is a person rather than an error message.
Done properly, none of this is visible to whoever is booking.
They answer two questions, pick a time, and speak to the right person. That is the entire objective; everything above is plumbing.
appointment schedulingavailability managementB2B toolsbusiness operationsbusiness workflowcalendar managementcalendar optimizationmeeting planningmeeting routingoperational efficiencyproductivity toolsremote work toolsround robin schedulingschedulingsmall team managementsoftware configurationteam collaborationteam productivitytime managementworkflow automation
Artikel terkait lainnya